Plate artifacts and corrections#
Plates drift, well position matters, and cell count affects most features. This page looks for those artifacts
on a real screen, pki: eight plates of kinase inhibitors from the JUMP pilot [Chandrasekaran et al., 2023]. It
removes them and measures whether removing them helped.
Every correction here can make results worse on a given dataset. The last section shows a real case where sphering, a standard step of the pipeline, cuts mechanism retrieval by more than three quarters.
import warnings

import numpy as np
import pandas as pd
import scanpy as sc

import mantispy as mt
from mantispy._core.plate import well_col, well_row

warnings.formatwarning = lambda message, category, *a, **k: f"{category.__name__}: {message}\n"

wells = mt.ds.pki()
mt.pp.normalize(wells, method="mad_robustize", by="Metadata_Plate", reference="negcon")
mt.pp.feature_select(wells, na_cutoff=0.0)
wells = mt.pp.subset_features(wells)
wells
AnnData object with n_obs × n_vars = 3072 × 850
    obs: 'Metadata_plate_map_name', 'Metadata_broad_sample', 'Metadata_mg_per_ml', 'Metadata_mmoles_per_liter', 'Metadata_solvent', 'Metadata_Plate', 'Metadata_Well', 'Metadata_Site_Count', 'Metadata_Count_Cells', 'Metadata_Count_CellsIncludingEdges', 'Metadata_Count_Cytoplasm', 'Metadata_Count_Nuclei', 'Metadata_Count_NucleiIncludingEdges', 'Metadata_Object_Count', 'Metadata_Barcode', 'Metadata_Supplier', 'Metadata_Supplier_Catalog', 'Metadata_pert_type', 'Metadata_control_type', 'Metadata_CellCount', 'Metadata_SiteCount', 'Metadata_Control', 'Metadata_Compound', 'Metadata_Concentration', 'Metadata_MOA', 'Metadata_Perturbation', 'Metadata_Perturbation_Type'
    var: 'object', 'feature_group', 'feature', 'channel', 'scale', 'angle', 'gray_levels', 'radial_bin', 'params', 'is_feature', 'degenerate_scale', 'selected'
    uns: 'mantispy'
    layers: None (.X)
Position effects#
Edge wells evaporate, corners sit at a different temperature, and dispensing drifts along a row.
pl.plate_effects shows the row and column medians of each plate. A position artifact appears as a trend across
rows or columns, while noise scatters around the plate median. Two of the eight plates:
Correcting is not free. A row and column effect fitted from a few dozen control wells can fit their own scatter, and subtracting it strips signal rather than an artifact. detect_plate_position cross-validates the same median polish on held-out controls and reports, per plate, whether the fit generalizes, so you can correct only the plates where the effect is real instead of every plate.
two = wells[wells.obs["Metadata_Plate"].isin(wells.obs["Metadata_Plate"].cat.categories[:2]).to_numpy()].copy()
mt.pl.plate_effects(two);
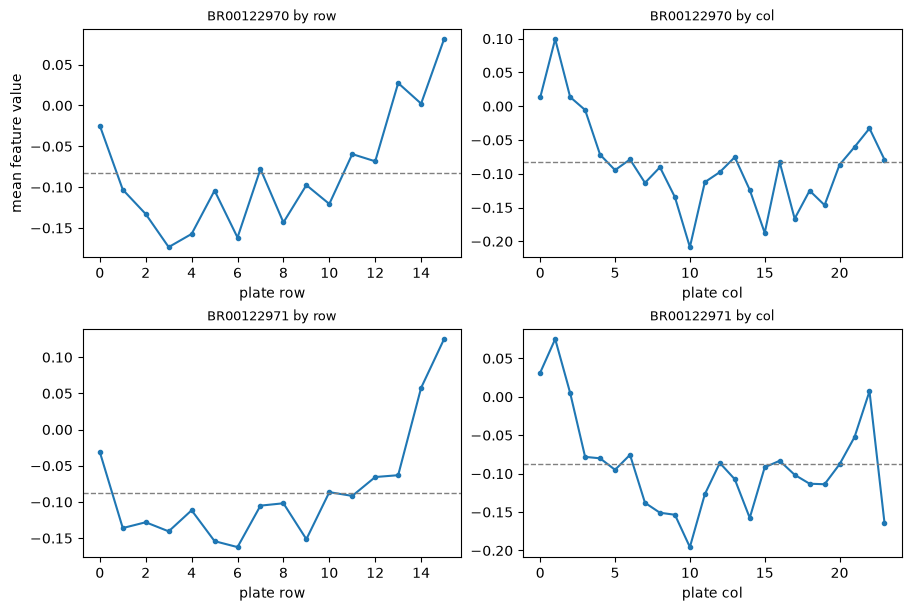
correct_plate_position fits Tukey’s median polish to the row and column effects of each plate, so a few extreme wells do not define the gradient. Its default, method="b_score", then divides the residual by the plate’s MAD (median absolute deviation), which resists outliers and gives a position-corrected z-score per plate. The z-score is the screening standard for calling hits against a gradient, and the plate-position case study shows it on data. Here we use method="median_polish", which subtracts the effects and keeps each feature’s units, so we can read how much of each feature position explains, before and after, as its correlation with the row and the column it sits in:
rows = np.array([well_row(well) for well in wells.obs["Metadata_Well"]])
columns = np.array([well_col(well) for well in wells.obs["Metadata_Well"]])


def position(adata):
    """Median and largest absolute correlation of a feature with its well's row and column."""
    values = np.asarray(adata.X, dtype=float)
    result = {}
    for name, axis in (("row", rows), ("column", columns)):
        r = np.abs([np.corrcoef(axis, values[:, j])[0, 1] for j in range(values.shape[1])])
        result[f"{name}: median |r|"] = round(float(np.nanmedian(r)), 3)
        result[f"{name}: largest |r|"] = round(float(np.nanmax(r)), 3)
    return result


corrected = mt.pp.correct_plate_position(wells, method="median_polish", copy=True)
pd.DataFrame({"before": position(wells), "after": position(corrected)})
| before | after | |
|---|---|---|
| row: median |r| | 0.055 | 0.012 |
| row: largest |r| | 0.316 | 0.132 |
| column: median |r| | 0.070 | 0.021 |
| column: largest |r| | 0.692 | 0.131 |
Position explains little of most features and a lot of a few. Before correction the median feature correlates with its well’s column at 0.07, and the most affected one at 0.69; median polish takes the largest correlation with the row or the column to about 0.13.
If treatments are laid out by column, fit the effects on the controls only, with
reference="negcon", so that treatment effects are not absorbed into a column effect and
subtracted.
This has a limit. A median polish can only fit a column effect for columns that contain reference rows, and most layouts put the controls in a few fixed columns, such as 1 and 2 or 23 and 24. With controls in four of twenty-four columns there is no control-only column effect to fit. Row effects still work, because controls in an edge column span every row. For column effects on a column-wise layout, the design has confounded the effect you want to correct, and the fix is a randomized layout on the next plate.
Whether to correct at all, and how to tell, turns on what you are measuring. The plate-position case study works through it on real data. The correction helps hit-calling against a gradient, and it removes signal from multivariate profiles. detect_plate_position is how you decide per plate, or flag a plate for exclusion.
Confounders#
Cell count is the most common one: a sparse well looks different from a confluent one regardless of treatment.
regress_out fits each feature against the confounder within each plate and keeps the residual.
The fit has to be made on wells whose density varies for technical reasons only. In a compound screen the
treatments change density too, and a compound that thins its wells usually has a phenotype of its own, so a fit
over every well mistakes that phenotype for a density effect. reference="negcon" fits on the DMSO wells, keeps
them where normalization centred them, and corrects a well sparser or denser than any control as if it sat at the
edge of their range rather than by extrapolating.
counts = wells.obs["Metadata_CellCount"].to_numpy(dtype=float)
plates = wells.obs["Metadata_Plate"].astype(str).to_numpy()
control = wells.obs["Metadata_Control"].to_numpy(dtype=bool)


def density(adata):
    """How much of each feature follows the cell count, and whether the controls stay centred."""
    values = np.asarray(adata.X, dtype=float)
    within = []
    for plate in np.unique(plates):
        rows = (plates == plate) & control
        r = [np.corrcoef(counts[rows], values[rows, j])[0, 1] for j in range(values.shape[1])]
        within.append(np.nanmedian(np.abs(r)))
    every = [np.corrcoef(counts, values[:, j])[0, 1] for j in range(values.shape[1])]
    return {
        "DMSO wells, within plates: median |r|": round(float(np.median(within)), 3),
        "every well: median |r|": round(float(np.nanmedian(np.abs(every))), 3),
        "DMSO wells off centre": round(float(np.median(np.abs(np.median(values[control], axis=0)))), 3),
    }


print(
    "median cells per well, by plate:",
    wells.obs.groupby("Metadata_Plate", observed=True)["Metadata_CellCount"].median().to_dict(),
)

fit_on_everything = mt.pp.regress_out(wells, keys=("Metadata_CellCount",), by="Metadata_Plate", copy=True)
fit_on_controls = mt.pp.regress_out(
    wells, keys=("Metadata_CellCount",), by="Metadata_Plate", reference="negcon", copy=True
)
pd.DataFrame(
    {
        "before": density(wells),
        "fit on every well": density(fit_on_everything),
        "fit on the DMSO wells": density(fit_on_controls),
    }
)
median cells per well, by plate: {'BR00122970': 1974.5, 'BR00122971': 1956.0, 'BR00122972': 607.5, 'BR00122973': 602.5, 'BR00122974': 1640.0, 'BR00122975': 1631.0, 'BR00122977': 1820.0, 'BR00122978': 1803.5}
| before | fit on every well | fit on the DMSO wells | |
|---|---|---|---|
| DMSO wells, within plates: median |r| | 0.179 | 0.193 | 0.000 |
| every well: median |r| | 0.142 | 0.546 | 0.132 |
| DMSO wells off centre | 0.000 | 0.409 | 0.014 |
Two of the eight plates hold about a third of the others’ cells. Fitted on every well, each plate’s fit is
re-expressed at the density of the whole screen, which those two plates never reach, so their correction is an
extrapolation, and regress_out warns about it. The result follows the cell count more closely than before across
the screen, 0.55 against 0.14, and the DMSO wells end 0.41 off the centre normalization gave them.
Fitted on the DMSO wells, the correction removes the count’s pull on them, zero by construction since the fit was made on them, and leaves them centred. Across every well the correlation stays about where it was. What remains there is mostly the treatments’ own effect: a compound that thins its wells also changes the cells that are left, and a correction for technical density should not remove that.
Missing values stay missing. Imputing them for the regression and writing the fitted value back would make an unmeasured value look like a real measurement.
Plates as batches#
A batch effect moves the controls too. pl.control_drift projects the control wells onto components fitted on the
controls alone, so if the controls of different plates land in different places, the reference itself shifts
between them.
mt.pl.control_drift(wells, groupby="Metadata_Plate");
Measuring the result#
mt.metrics scores a representation with several metrics. Batch-mixing metrics and biological-signal metrics
trade off against each other, and a correction that improves one at the expense of the other has not helped.
Normalizing each plate against its own controls is itself a batch correction. Here it is measured against one normalization pooled over the whole screen, on the same features:
mt.metrics.evaluate_integration runs the integration benchmark from
scib-metrics, the field’s implementation, which mantispy imports rather
than reimplements. Install it with pip install "mantispy[integration,map]". It reads scib-metrics’ public
results and draws its own heatmap, one row per representation, with the columns grouped into blocks: bio
conservation, batch correction, retrieval, and the aggregate scores. Higher is better in every cell. cLISI is
how label-pure a well’s neighbourhood is (bio conservation); iLISI is how batch-mixed it is, and PCR comparison
is how much less of the variance the batch explains after correction (batch correction).
With copairs installed the heatmap gains a retrieval block, the
cross-replicate mean average precision (mAP), and a second aggregate column. Total is scib-metrics’ own
weighted score (0.4 batch correction, 0.6 bio conservation), left exactly as scib computes it; Total+mAP is
mantispy’s, which folds mAP into the bio group as one more bio signal. With only copairs it draws the mAP column
alone, and with neither it raises and points you to mt.metrics.batch_variance_explained (stack several
covariates) or mt.metrics.pc_regression (a single covariate) for a native batch-variance check.
pc_regression is deliberately not in this panel: whether a covariate’s share of the variance, such as the cell
count’s, should be small depends on the screen. The call returns the numeric results frame as well, so the
values are always reachable.
pooled = mt.ds.pki()
mt.pp.normalize(pooled, method="mad_robustize", by=None, reference="negcon")
pooled = pooled[:, wells.var_names].copy()

sc.pp.pca(wells, n_comps=20)
sc.pp.pca(pooled, n_comps=20)
wells.obsm["X_pooled"] = pooled.obsm["X_pca"]

mt.metrics.evaluate_integration(
    wells, reps=("X_pca", "X_pooled"), label_key="Metadata_Perturbation", batch_key="Metadata_Plate"
);
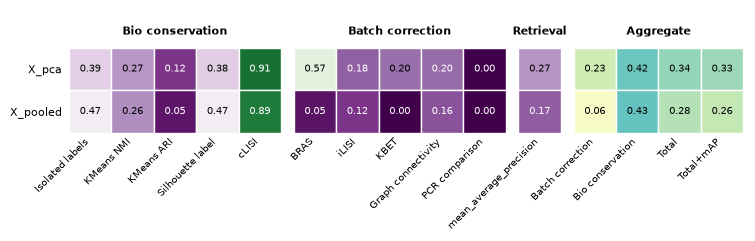
Read the heatmap by column, where higher is better everywhere. The aggregate block on the right carries two
totals: scib-metrics’ Total weights bio conservation at 0.6 against batch correction at 0.4, and mantispy’s
Total+mAP folds the retrieval block into the bio group before the same weighting. X_pca is the per-plate
normalization and X_pooled the pooled one; per-plate scores higher on batch correction, because scoring each
plate against its own controls takes the plate’s share of the variance out, and a well’s neighbours then come
from more plates. It gives a little bio conservation back in return, the trade-off these metrics are built to
show, which is why the pages that follow judge a correction by retrieval, the question a screen asks. The
retrieval block is that mAP, cross-replicate here.
pl.batch_variance shows the plate’s share per component, which tells you where in the embedding it sits.
mt.pl.batch_variance(wells, keys=["Metadata_Plate", "Metadata_Perturbation"], use_rep="X_pca");
Harmony, the last step of the JUMP recipe, corrects an embedding rather than the features.
Reproducing across laboratories runs it on JUMP and measures the result.
For a correction on the features instead of an embedding, sc.pp.combat is the usual choice.
Sphering, and a correction that makes things worse#
Sphering is typical variation normalization. The covariance of the negative controls describes variation that is
not of interest, and whitening removes it, leaving the variation caused by the perturbations. ZCA-cor is the
default because it rotates back into the original feature basis, so the columns still match var.
Sphering needs more control wells than features. BBBC021 [Ljosa et al., 2013] has few control wells for the features that survive selection, so its control covariance is singular. Score mechanism retrieval with and without sphering, with the not-same-compound rule from Mechanism of action.
def not_same_compound(adata):
    """Not-same-compound mechanism retrieval on one signature per treatment."""
    treated = adata[~adata.obs["Metadata_Control"].to_numpy()].copy()
    signatures = mt.tl.consensus(treated, method="median", min_replicates=1)
    signatures = signatures[signatures.obs["Metadata_MOA"].notna().to_numpy()].copy()
    mt.tl.nn_moa_classify(signatures, scheme="nsc")
    return round(signatures.uns["mantispy"]["moa"]["accuracy"], 3)


bbbc = mt.ds.bbbc021()
mt.pp.normalize(bbbc, method="mad_robustize", by="Metadata_Plate", reference="negcon")
mt.pp.feature_select(bbbc, na_cutoff=0.0)
bbbc = mt.pp.subset_features(bbbc)

sphered = bbbc.copy()
with warnings.catch_warnings(record=True) as caught:
    warnings.simplefilter("always")
    mt.pp.sphere(sphered, method="ZCA-cor", reference="negcon")
print(caught[0].message)

{
    "control wells": int(bbbc.obs["Metadata_Control"].sum()),
    "features": bbbc.n_vars,
    "without sphering": not_same_compound(bbbc),
    "with sphering": not_same_compound(sphered),
}
sphering is fitted on 330 reference rows for 343 features. With fewer rows than features the covariance is singular and the transform amplifies noise. Select fewer features first, or use more controls.
{'control wells': 330,
 'features': 343,
 'without sphering': 0.777,
 'with sphering': 0.175}
Sphering cuts not-same-compound accuracy from 0.78 to 0.18, a loss of more than three quarters, on 330 control wells for 343 features. mantispy’s sphering is tested against pycytominer’s, so pycytominer should show the same drop.
Measure a correction on the question the screen asks before adopting it. For this dataset, either select fewer features so the control covariance is well determined, or skip sphering.
Next: Is the screen any good?